
AI & Agents · Systems
swift-qwen3.8-rtx3090
A reproducible pipeline that rebuilds a 27B finetune into a fast single-RTX-3090 variant. It derives the draft vocabulary and int4 GPTQ calibration from the model's own outputs, which lifts draftable-token coverage from 96.7% to 99.8% and decode from 94.0 to 98.4 tokens per second, level with syv's fast build of base Qwen.
Active · 2026
Python · vLLM · GPTQ · RTX 3090
My coding agent runs against a local model, not an API. The machine is a single RTX 3090, and the stack that makes 27B Parameters The learned numbers inside a model. 27B means 27 billion of them, and all of them have to fit in GPU memory. usable on it is syv’s HyperQwen. It pins and patches vLLM An open-source server for running large language models (LLMs) on GPUs. The v comes from the virtual-memory technique it uses to manage the context. It handles memory, batching and speculative decoding., keeps the Body The stack of transformer layers between the embeddings and the lm_head. Each layer turns a hidden state into the next one, and together they hold most of the parameters. at Quantisation Storing a model's weights with fewer bits, for example 4 instead of 16. The model gets smaller and faster to read from memory, at some cost in accuracy., and requantises the Heads The two vocabulary-sized tables at either end of the body. The embeddings turn tokens into numbers on the way in, and the lm_head turns numbers back into token scores on the way out. Swift's 4-bit export left them unquantised, so the serving stack quantises them separately. and the MTP Multi-token prediction. A small module shipped with the model that cheaply guesses the next few tokens, so the full model can check several at once instead of producing them one by one. draft module so the whole thing fits in VRAM Video RAM, the GPU's own memory. The RTX 3090 has 24 GB, and the weights, the context and working buffers all have to fit in it. with a 114k Context window How many tokens the model can see at once, including the whole conversation so far. 114k tokens is a few hundred pages of text..
Stock Qwen3.8-27B reasons too much for my use. On two open-ended code tasks it spent the full 8,192-Token A chunk of text the model reads and writes, usually a word or part of one. Speed, context length and output are all counted in tokens. Thinking tokens Reasoning models write out a private chain of thought before answering. Those tokens take as long to generate as the answer does, and the budget caps how many the model may spend. and never wrote any code. Swift, a community Finetune A copy of an existing model trained further on new data to change its behaviour. Swift is Qwen3.8-27B trained to reason more briefly. tuned for shorter reasoning, finished the same tasks in 2,500 to 7,100 thinking tokens and produced working code. No Decode Generating the answer one token at a time after the prompt has been read. Decode speed is measured in tokens per second.-speed trick closes a gap like that, so I switched.
The syv stack will serve Swift, but as a third-party Checkpoint A saved set of model weights on disk. It is the thing you download when you download a model., and those get a lower tier of support than base Qwen. Base Qwen has a “fast variant” with an int4 and int8 Integers, meaning whole numbers, stored in 4 or 8 bits. An int4 weight takes a quarter of the memory of a 16-bit one, at the cost of coarser rounding. GPTQ A quantisation method named after GPT (generative pre-trained transformer) models, with Q for quantisation. It rounds weights one column at a time and nudges the remaining weights to cancel out the error so far. It needs sample data from the model to know which errors matter. lm_head Short for language-model head, the model's final layer. It turns the last hidden state into a score for every token in the vocabulary, about 248,000 of them, and the top score becomes the next token. and draft module, plus a Draft vocabulary The list of tokens the drafter is allowed to guess. Scoring 40,960 candidates instead of all 248k is much cheaper, but the drafter can never guess a token that is not on the list. counted over the model’s own outputs. That variant is worth about 15 percent. Third-party checkpoints get int8 heads and base Qwen’s draft vocabulary. Swift ran fine that way. I wanted to know how much of the fast variant’s gain I could get back by rebuilding it for Swift.
Body, heads and drafter
A checkpoint in this stack has three parts, and the fast variant leaves the biggest one alone.
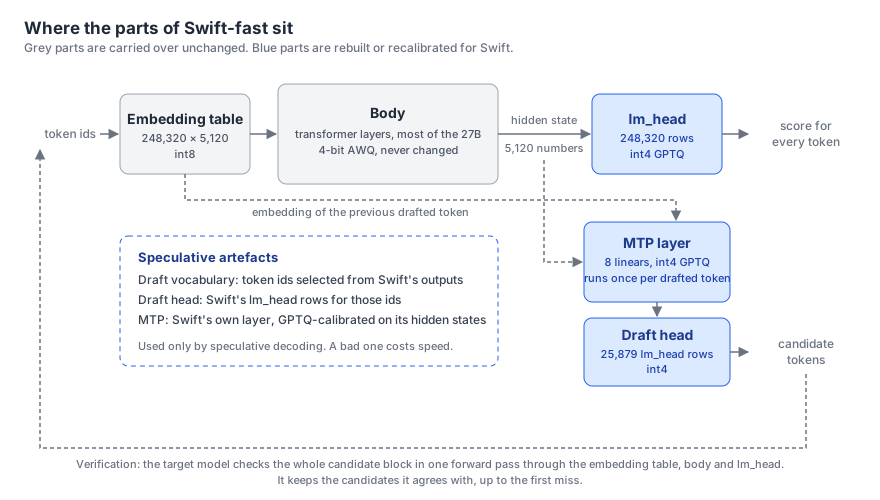
The body is the stack of transformer layers in the middle, and it holds most of the 27B parameters. Each layer reads a Hidden states The model's internal numbers at a given layer while it processes a token. The last layer's hidden state is what the lm_head and the MTP module read. of 5,120 numbers per token and writes an updated one. Swift’s body is a 4-bit AWQ Short for activation-aware weight quantisation. A 4-bit method that protects the weights that matter most for real inputs. TheUnderscore used it to shrink Swift to 4-bit. export. I never change it.
The heads sit at either end of the body, with one row per token in the 248k vocabulary. Strictly, only the lm_head is a head, but the syv stack quantises the two tables together and calls them the heads, so I do too. The Embeddings The table that turns each input token into the list of numbers the model works with. It is the mirror image of the lm_head. turn a token into its first 5,120 numbers. The lm_head turns the last hidden state into a score for every token. At 248k by 5,120, each table is about 1.3 billion parameters, and the AWQ export leaves both unquantised. Swift’s int8 build quantises them to int8.
Only one of them is worth shrinking further. vLLM reads the whole lm_head on every decode step, so the fast variant takes it to int4. A token only reads its own row of the embeddings, so they stay at int8.
The drafter is the MTP module. It is one extra transformer layer plus an input projection, eight Linear layer A layer that multiplies its input by a matrix of weights. Most of the parameters in a model live in layers like these. in all. The projection mixes two inputs, the body’s last hidden state and the embedding of the previous drafted token. The drafter runs once per guess, feeding each drafted token back in to guess the next. To score those guesses it uses a draft head, a slice of the lm_head with rows only for the tokens in the draft vocabulary. For Swift that is 25,879 rows.
The draft vocabulary, the draft head and the MTP weights exist only for Speculative decoding A cheap drafter guesses several tokens ahead and the full model checks them all in one pass. The model keeps the correct guesses and throws away everything from the first wrong one onwards., so I call them the speculative artefacts. None of them are newly trained. The vocabulary is a count over Swift’s outputs, and the MTP weights are Swift’s own, requantised against its hidden states. The full model then checks the whole block of drafted tokens in one forward pass through the embeddings, body and lm_head, and keeps them up to the first one it disagrees with. A bad artefact makes the model slower, never wrong.
Speculative artefacts depend on the model
The MTP drafter scores a 40,960-row slice of lm_head instead of the full 248k vocabulary. It can never draft a token outside that slice. Every miss is a guaranteed rejection, and a rejection ends the speculation chain, so misses cost more than their share of tokens.
The shipped slice was counted over base Qwen’s outputs. Against what Swift actually generates, it covered 96.7 percent of tokens. That sounds fine until you look at where the other 3.3 percent sits. It is code and Tool call Structured output an agent emits to run something, such as reading a file or running a test. It has strict syntax, so one wrong token breaks it. syntax, which is most of what my agent emits.
GPTQ calibration has the same problem. The Hessian A matrix of second derivatives. In quantisation it is built from real inputs to a layer and measures how much an error in each weight would change the layer's output, so GPTQ knows where rounding hurts most. you quantise against comes from the hidden states that feed the layer. States captured from base Qwen are the wrong calibration for a finetune that writes differently.
So I redid the fast-variant recipe with every input derived from Swift. The syv repo already had the recipe as scripts under drafter/, and I ran them unmodified. The work was feeding them the right corpus and handling a checkpoint layout they did not expect. Swift’s AWQ export splits lm_head, embeddings and MTP across separate Shard Large models are split across several weight files called shards. An index file records which shard holds each tensor., and upstream’s quantisation scripts assumed base Qwen’s single-shard layout.
Corpus, outputs, vocabulary
Upstream built its draft vocabulary from a Danish-heavy chat mix. That suits the people who wrote it and says little about a Rust coding agent. I wrote a generator that emits 5,500 prompts weighted by my workload. 35 percent is Rust implementation work, 16 percent TypeScript, 12 percent debugging from symptoms, 10 percent code edits and 8 percent tool-use transcripts. The rest is architecture questions, reasoning puzzles and general chat. About 60 percent of prompts run with thinking on, because that is how I use the model day to day. The generator is seeded, so the same config always produces the same corpus.
Running 3,072 of those prompts through Swift took about 1.7 GPU-hours and produced 4.2 million output tokens. I stopped there because Held-out data Data set aside and not used to build something, so it can test that thing fairly. Measuring on the same data you built from flatters the result. coverage had flattened. A vocabulary built from the first quarter of the data already covered 99.17 percent of held-out outputs, and the full run only reached 99.81.
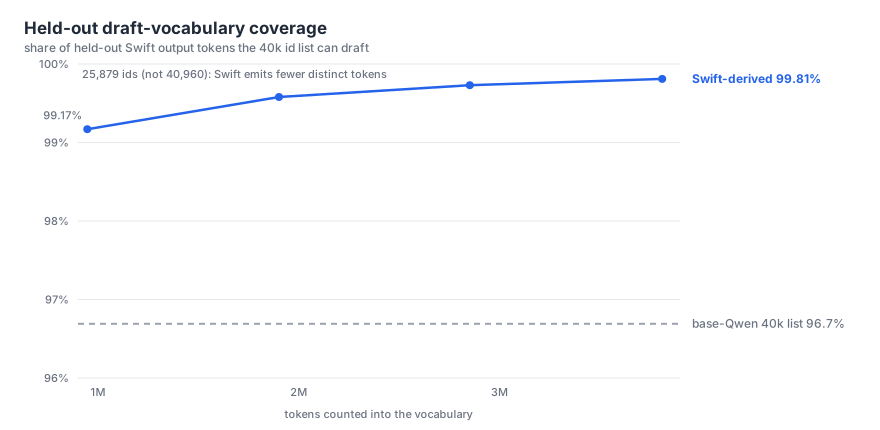
The vocabulary is a frequency count over 90 percent of those outputs, with special tokens forced in and everything else ranked by count. The other 10 percent, 417k tokens, is the held-out set. Against it, coverage went from 96.7 to 99.81 percent, and to 99.86 on code prompts.
The overlap surprised me more. Only 18,701 of base Qwen’s 40,960 ids appear in Swift’s list at all. Swift’s corpus only ever emitted 25,879 distinct tokens, so the right list is shorter than the slot count. Any check that demands exactly 40,960 rows is wrong for this model, which mattered when I came to write the verifier.
GPTQ heads
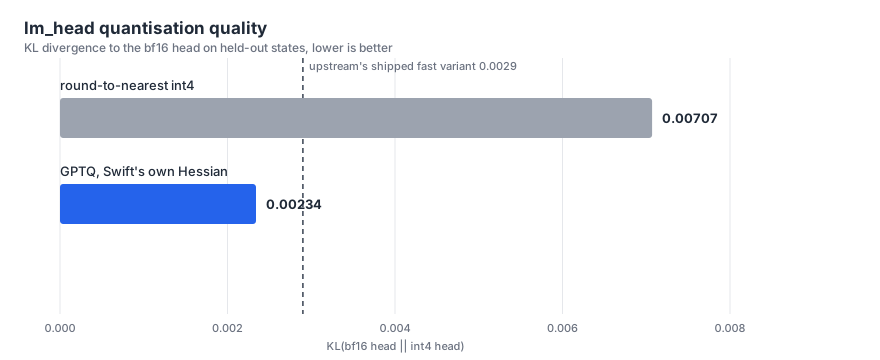
With outputs in hand, the rest is upstream’s recipe. Capture hidden states for every token, dump the MTP Hessians, then GPTQ the lm_head and the eight MTP linears to int4 against them. I judged the lm_head by KL divergence Kullback-Leibler divergence, a measure of how different two probability distributions are, where zero means identical. This write-up uses it to compare the quantised head's next-token probabilities with the full-precision head's. from the bf16 Short for brain floating point 16, a 16-bit number format from Google Brain that most models are trained and shipped in. It is the full-quality reference that quantised versions get compared against. head on held-out states. Round-to-nearest The simplest quantisation. Round each weight to the closest value the smaller format can hold and do nothing about the error. int4 scored 0.00707. GPTQ on Swift’s own Hessian scored 0.00234, lower than the 0.0029 that base Qwen’s fast variant shipped at on its own states.
The bug that earned a verifier
The fast directory shares body shards with the int8 directory through Hardlink A second filename that points at the same data on disk. Two folders can share a 15 GB file without storing it twice, and a write through either name changes both., so a 15.2 GB variant costs almost nothing extra on disk. The catch is that vLLM reads every key of every shard it opens, not only the Tensor A named block of numbers, such as one layer's weight matrix. A model file is a collection of tensors. the index assigns to that shard.
My first build hardlinked model-nonquant.safetensors, which still carried the int8 MTP tensors from the int8 build. The new int4 tensors lived in model_extra_tensors.safetensors. vLLM loaded both, and the boot died on a shape assertion that named neither file. Every existence check passed, because every mapped tensor existed in the right shard exactly once. Nothing looked at the other shards. Had the shapes matched, whichever copy loaded last would have won, and I would have served the wrong weights without an error.
Upstream’s verify.sh couldn’t help. It hard-required an int8 lm_head, so it rejected every int4 fast variant, base Qwen’s included. Until I had something better, my fast directory booted with VERIFY=0.
So I wrote a structural verifier before making the fast variant my default boot target. It reads safetensors A file format for model weights. Each file starts with a header listing every tensor's name, shape and position, so tools can inspect it without loading the weights. headers directly and needs no torch. It checks that packed and scale shapes match the bit widths the config declares, that the draft head has one row per id in the draft vocabulary, and that every index-mapped tensor lives in exactly one shard, the one the index names. That last check catches the collision before anything boots. The repo ships a stdlib-only selftest that builds toy model directories, corrupts each one in a specific way, and asserts the verifier rejects all of them. The stale-tensor collision is one of the fixtures.
Results
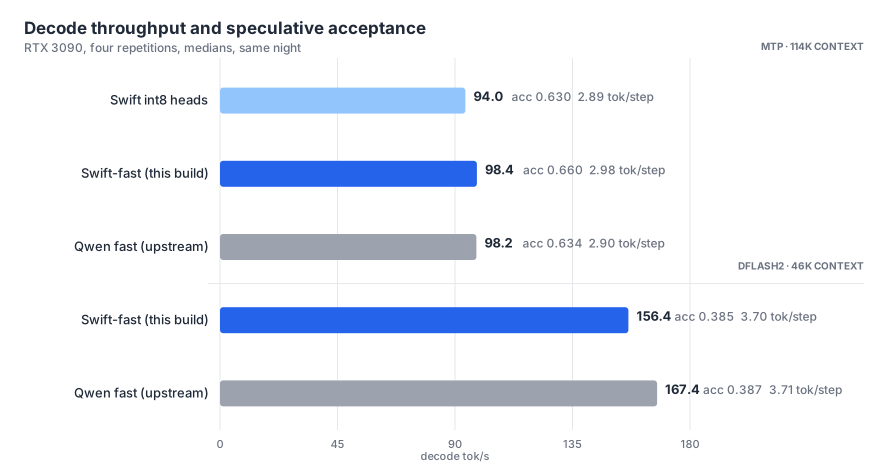
All five configurations ran the same night with four repetitions each, and the table shows medians. Decode is tokens per second. Acceptance The share of drafted tokens the full model agrees with and keeps. Higher acceptance means more tokens per pass and faster output. is the fraction of drafted tokens the target kept, read from vLLM’s own speculative-decoding counters. Tok/step is tokens produced per Forward pass One run of the full model over its input. A pass costs about the same time whether it produces one token or four, which is why drafting pays off..
| variant | decode | acceptance | tok/step | VRAM MiB |
|---|---|---|---|---|
| Swift int8, MTP long | 94.0 | 0.630 | 2.89 | 22085 |
| Swift-fast, MTP long | 98.4 | 0.660 | 2.98 | 22225 |
| Qwen fast, MTP long | 98.2 | 0.634 | 2.90 | 22191 |
| Swift-fast, DFlash2 | 156.4 | 0.385 | 3.70 | 23081 |
| Qwen fast, DFlash2 | 167.4 | 0.387 | 3.71 | 23007 |
MTP with the long context is my daily profile. There, Swift-fast decodes 4.7 percent faster than Swift’s int8 build and matches base Qwen’s fast variant, 98.4 against 98.2 tokens per second, with higher acceptance. A separate quote benchmark asks the model to reproduce 8,000 tokens of its own context verbatim. Swift-fast drafts it at 0.998 acceptance and 3.99 tokens per step against a ceiling of 4, up from 0.962 on the int8 build.
The DFlash2 A separate, larger drafter the stack supports as an alternative to MTP. It guesses more tokens per step, so it decodes faster, but on a 24 GB card it leaves room for only a 46k-token context. profile is faster on paper, and I still don’t use it as the default. It caps context at 46k tokens, and my agent’s wall time depends on how many reasoning tokens a task takes and whether it finishes, more than on raw decode. In my agent-latency runs, Swift-fast and Qwen-fast finished the same share of tasks, and long agent sessions need the 114k context more than the extra speed.
The new vocabulary helped DFlash2 anyway. On an earlier night, Swift’s DFlash2 acceptance trailed Qwen’s, 0.367 against 0.387. It now sits at 0.385, which is noise. The remaining gap of 156 against 167 tokens per second comes from the AWQ body reading about 0.24 GiB more weight bytes per step than Qwen’s AutoRound A 4-bit quantisation method. Base Qwen's body in this stack uses it, and it reads fewer bytes per step than Swift's AWQ body. body. No drafter fixes that. Requantising the body would, but it means a 55 GB source download and more GPU hours to win back 7 percent on a profile I don’t run daily. I skipped it.
Quality held. On a nine-task battery with mechanical checks, the fast variant passed 8 of 9, the same set as the int8 build. The failure is a hard combinatorics problem that both models get right on some samples and wrong on others. I saw no regressions in how reasoning terminates.
Splitting the work
Two of the fixes weren’t specific to Swift, so I sent them upstream. PR 122 makes verify.sh accept the int4 lm_head layout and checks the packed shape against the declared bit width. PR 123 adds the duplicate-tensor scan. syv merged both.
The target-specific pipeline stayed in my repo, swift-qwen3.8-rtx3090. A workload mix is an opinion about one person’s usage, and HyperQwen is deliberately model-agnostic. The repo runs upstream’s scripts rather than forking them, and adds the corpus generator, vocabulary builder, head quantisation and verifier around them.
Publishing the weights
The finished model is on the Hugging Face Hub The main public host for model weights and datasets. Think GitHub, but for models. as liamwh/Swift-Qwen3.8-27B-W4A16-syv-fast. It serves directly on the syv stack with no preparation step. The model card carries both licences the Swift Open License requires of derivatives, and traces the provenance from Alibaba through UkisAI and TheUnderscore to this pipeline.
The upload was much smaller than the model. The AWQ body shards are byte-for-byte identical to TheUnderscore’s checkpoint, so Xet Hugging Face's storage backend. It splits files into chunks and only uploads chunks it has not already stored. deduplication only transferred what I changed: the int4 heads, the MTP tensors, the extra tensors and the model card. About 2 GB of upload published a 15.2 GB model.
The pipeline repo still contains no weights. If you want to run Swift-fast, download the published model. If you want to rebuild it, or build the same thing for another Qwen3.8-family finetune, use the pipeline with a checkpoint you’re licensed to use. Edit the workload mix first. The draft vocabulary is only as good as the corpus behind it.